Overview
Hebrew is less well served by general-purpose models than English. The question was whether a small, fine-tuned Hebrew model could do better on sentiment than prompting a large general model.
What I built
- Fine-tuning. DictaBERT fine-tuned with LoRA on 43,600 labelled examples.
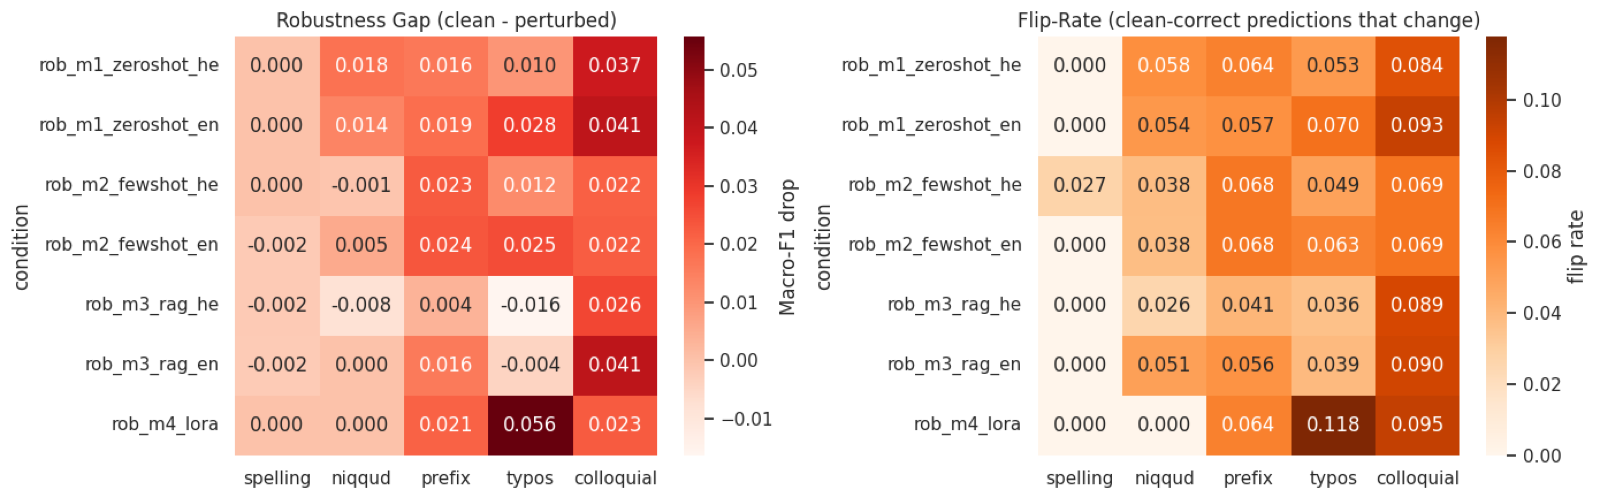
- Baselines. GPT-4o zero-shot, few-shot and a RAG setup, all evaluated with Macro F1.
- Result. The fine-tuned model outperformed the GPT-4o and RAG baselines.
Transformer from scratch
Separately, I implemented a GPT-style transformer from scratch in PyTorch, including self-attention, causal masking and LayerNorm, to understand the architecture below the library level.
Screenshots
Next project
World Cup 2026 Forecast